Platform Live · 179 API Endpoints · 77 Tables

The Token Intelligence Infrastructure Layer

Route LLM requests with sub-millisecond cache hits. Benchmark models with 5-dimension TQS scoring. Bill tokens at microcent precision. Enterprise SSO, team budgets, and webhooks — all production-ready.

179
API Endpoints
77
DB Tables
<2ms
Cache Latency
10
Platform Modules
99.9%
Uptime SLA
Supported LLM Providers & Protocols
🤖 OpenAI GPT-4o 🧠 Anthropic Claude 🔮 Google Gemini 🌊 DeepSeek V3 💡 Mistral Large 🦙 Meta Llama 3 🔵 Cohere Command 🟢 OpenAI Embeddings Groq LLaMA-3 🌐 Any OpenAI-Compatible 🤖 OpenAI GPT-4o 🧠 Anthropic Claude 🔮 Google Gemini 🌊 DeepSeek V3 💡 Mistral Large 🦙 Meta Llama 3 🔵 Cohere Command 🟢 OpenAI Embeddings Groq LLaMA-3 🌐 Any OpenAI-Compatible

Everything your AI product needs.
Nothing it doesn't.

A unified infrastructure layer: gateway, cache, billing, security, and analytics — purpose-built for token-at-scale operations.
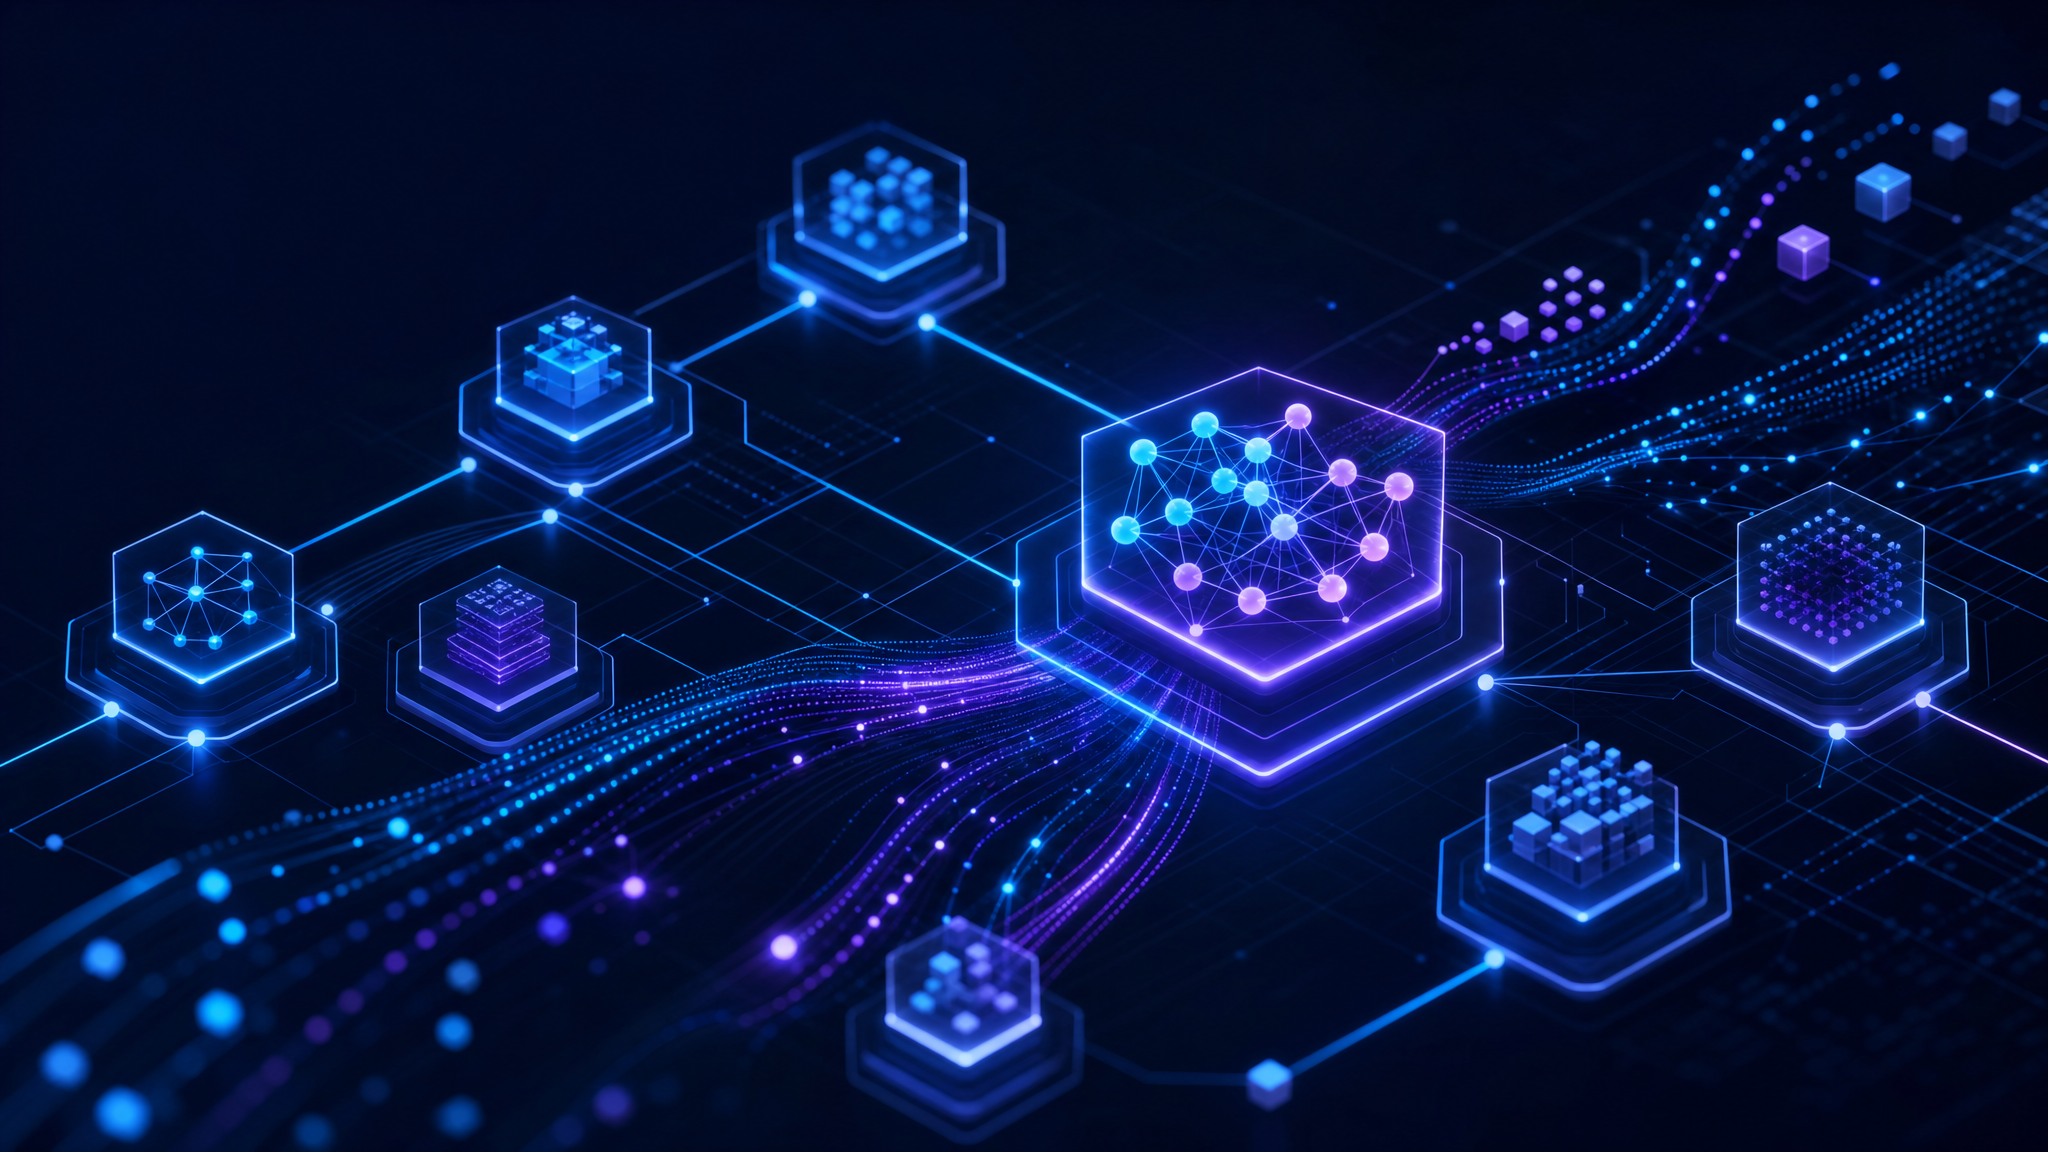
TokenStrata Platform Architecture

Inference Gateway

Route requests across any LLM provider with automatic failover, rate limiting, and dual-auth (JWT + API keys). OpenAI-compatible endpoint out of the box.

🧮

Token Billing Engine

Microcent-precision billing (1 USD = 1,000,000 microcents). Per-model pricing, org wallets, Stripe integration, automated invoicing with PDF export.

📊

Analytics Intelligence™

Real-time dashboards, ensemble cost forecasting (linear + weighted MA + exponential), p95/p99 latency tracking, custom reports in JSON or CSV.

🔐

TokenVault™ + Security

AES-256-CBC secret storage, TOTP 2FA, SIEM event streaming, IP allowlisting, and full audit logging — enterprise-grade from day one.
Ten integrated modules.
One unified platform.

Each module is fully deployed, live, and production-tested. No stubs, no mocks, no placeholders.

Core
🔑

Auth & API Keys

JWT authentication, scoped API keys with per-key rate limits, RBAC with 4 roles, org isolation, and complete audit logging.

16
Endpoints
32
DB Tables
4
Auth Roles
Intelligence
🧠

ReasoningOS

Five reasoning strategies: CoT, ToT, ReAct, Self-Consistency, Decomposition. A/B testing engine with statistical significance tracking.

ReasoningOS
5
Strategies
A/B
Testing
Performance

HyperCaching

Two-tier semantic cache: L0 exact-match (Redis) + L1 TQS similarity (n-gram TF-IDF, 128-dim). Up to 95% cost reduction on repeated queries.

HyperCache
L0+L1
Cache Tiers
95%
Cost Savings
Market
📈

SmartMarket

Token exchange marketplace: create listings, place bids, Buy Now, swaps, and peer-to-peer transfers. Real-time exchange rate engine (30-min refresh).

21
Endpoints
Live
Rates
Enterprise
👥

Team Management + SSO

Per-team token budgets, 5-role RBAC (47 permissions), invitation flows, and enterprise SSO: SAML, OIDC, Google, Azure AD, Okta, GitHub.

6
SSO Types
47
Permissions
Admin
🖥️

Admin Superpanel

Platform overview, org management, billing adjustments, model approvals, feature flags, platform settings, service metrics, and OpenAPI spec generation.

178
OpenAPI Ops
26
Webhook Events

Built for production
from the ground up.

Every layer is real, deployed, and tested. Laravel 12 + MySQL 8 + Redis + Apache on bare metal.

CLIENT
📱Mobile SDK
🌐Web App
⚙️Backend Service
🤖AI Agent
🔧CLI Tool
↓ HTTPS · JWT Bearer · ts_ API Keys ↓
GATEWAY
🔑Auth Guard
🚦Rate Limiter
HyperCache L0
🧮HyperCache L1
📊Request Logger
SERVICES
🧠ReasoningOS
📝PromptStudio
💰BillingEngine
🛡️TokenVault
📡Webhooks
DATA
🗄️MySQL 8.0
77 tables
Redis
cache+sessions
📁File Storage
reports+PDFs
🔮LLM Endpoints
any provider
179
Live API Endpoints
77
Database Tables
10
Platform Modules
<2ms
L0 Cache Latency
26
Webhook Event Types
6
SSO Providers

OpenAI-compatible.
Drop-in replacement.

Change one URL. Get caching, billing, observability, and team controls automatically.

inference.py
# Drop-in replacement for OpenAI client from openai import OpenAI client = OpenAI( api_key="ts_live_your_api_key", base_url="https://tokenstrata.com/api/v1" ) response = client.chat.completions.create( model="tokenstrata-prime", messages=[{ "role": "user", "content": "Analyse Q3 revenue trends" }] ) # Auto-cached, billed, logged ✓ # Cache status: X-Cache-Status: L1_HIT # Cost deducted: $0.000024 # Latency: 1.8ms (cache hit)
🔄

Dual Authentication

Accept both JWT Bearer tokens (for users) and ts_-prefixed API keys (for services). One endpoint, two auth paths.

Two-tier Semantic Cache

L0 exact-match in Redis (sub-1ms). L1 TQS similarity cache (128-dim n-gram TF-IDF) for near-duplicate queries. No external embedding API needed.

💰

Microcent Precision Billing

Every token tracked at 1/1,000,000 USD precision. Per-model pricing, pre/post-pay modes, wallet deduction atomic with request.

📊

Zero-config Observability

Every request logged: latency, tokens, cost, cache status, model, API key. Feeds analytics dashboards and cost forecasting automatically.

📖

Auto-generated OpenAPI Spec

Live OpenAPI 3.0 spec at /api/admin/openapi.json. 178 operations across 19 tags, always up-to-date with deployed routes.

Simple, transparent,
usage-based.

Pay for what you use. Scale without surprises. All plans include the full API surface.

Starter
$0/mo
Perfect for prototyping and low-volume applications.
  • 100K tokens/month included
  • 1 API key
  • HyperCaching™ (L0+L1)
  • Basic analytics dashboard
  • Community support
  • 1 user / 1 team
Get started free
Enterprise
Custom
Dedicated infrastructure, SLAs, and white-glove onboarding for large teams.
  • Unlimited tokens
  • Enterprise SSO (SAML/OIDC/Azure AD/Okta)
  • TokenVault™ + SIEM streaming
  • Custom billing models
  • Dedicated inference cluster
  • SLA 99.99% uptime
  • Unlimited users + teams
  • 24/7 dedicated support
Contact sales →

Teams scaling with
TokenStrata.

★★★★★
"We cut our LLM costs by 73% in the first week using HyperCaching™. The semantic L1 cache catches near-duplicate queries we didn't even know we had."
AK
Alex K.
CTO, FinTech AI Startup
★★★★★
"The billing precision is insane. Microcent tracking means we can offer pay-per-token pricing to our clients without any rounding errors or disputes."
SL
Sarah L.
Head of Platform, AI SaaS Co.
★★★★★
"Enterprise SSO with Azure AD + per-team budgets solved our entire enterprise sales blocker. Closed 3 Fortune 500 deals in one quarter."
MR
Marcus R.
VP Engineering, Enterprise AI

Your AI infrastructure.
Ready in 60 seconds.

One API key. Every LLM provider. Full billing, caching, and observability — live immediately.